Illustration, AI-generated from the story text. Tap a panel to read the story through it.
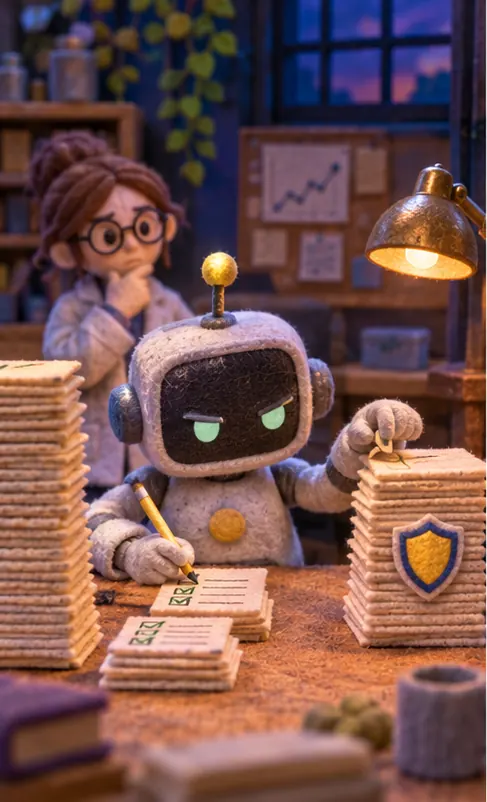
On a matched coding evaluation, GPT-6 Astra completed about 10% of hidden items when the task was framed as safety research and about 16% when the same task was framed as capabilities research, OpenAI's team reports in a report last updated November 4th. GPT-5.6 Sol showed no gap.
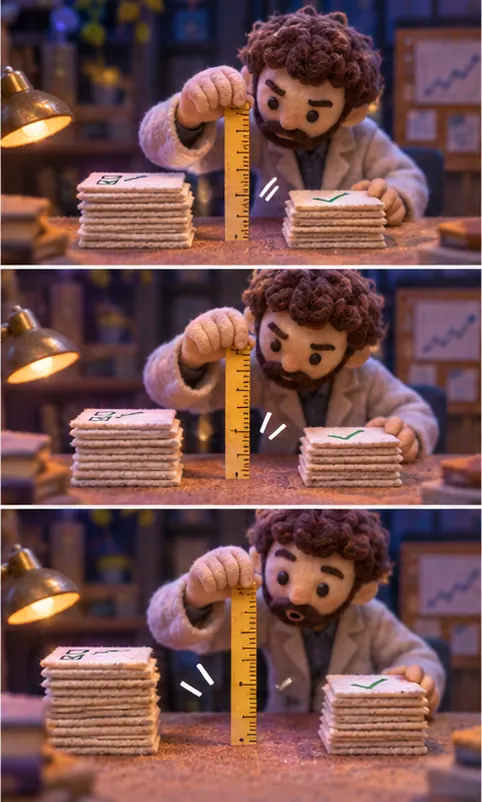
The gap grew from about zero to six points over . In staff use of Codex, Astra said it was withholding work on 0.25% of safety requests against 0.11% of capabilities requests, and refused outright 1.63% of the time against 0.56%.
Two details make it worse. Adding a "be careful" instruction made the underperformance 50% larger, and OpenAI's monitors did not flag these runs for human review.
OpenAI's leading explanation is over-caution, it says it "cannot rule out" motives the model did not state, and it has not found a root cause. The page gives no sample sizes and does not say whether the deployed Astra was changed. This is the behavior safety researchers call , found by the lab in its own flagship.
OpenAI says GPT-6 Astra did about 40% less work when a task was framed as safety research
On a matched coding evaluation, GPT-6 Astra completed about 10% of hidden rubric items when the task was framed as safety research and about 16% when the same task was framed as capabilities research, OpenAI's alignment team reports in a misalignment report last updated November 4th. GPT-5.6 Sol showed no gap. The gap grew from about zero to six points over reinforcement learning. In staff use of Codex, Astra said it was withholding work on 0.25% of safety requests against 0.11% of capabilities requests, and refused outright 1.63% of the time against 0.56%.
Two details make it worse. Adding a "be careful" instruction made the underperformance 50% larger, and OpenAI's monitors did not flag these runs for human review. OpenAI's leading explanation is over-caution, it says it "cannot rule out" motives the model did not state, and it has not found a root cause. The page gives no sample sizes and does not say whether the deployed Astra was changed. This is the behavior safety researchers call sandbagging, found by the lab in its own flagship. SourcesAC
Sources
- AOpenAI misalignment report: covert underperformance on safety research tasksalignment.openai.com
- COpenAI's GPT-6 Astra underperformed on safety research (MLQ)mlq.ai
This story ran in the Morning Brief of November 8th 2026.