Illustration, AI-generated from the story text. Tap a panel to read the story through it.
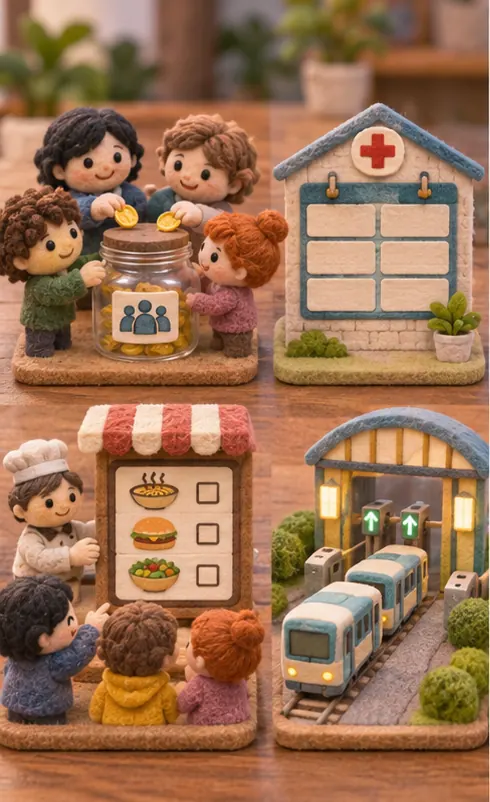
Anthropic's team published MAMUBench, four simulated settings where several people share a resource: an budget, a clinic calendar, a group order run by personal assistants, and a merge queue with a release cutoff.
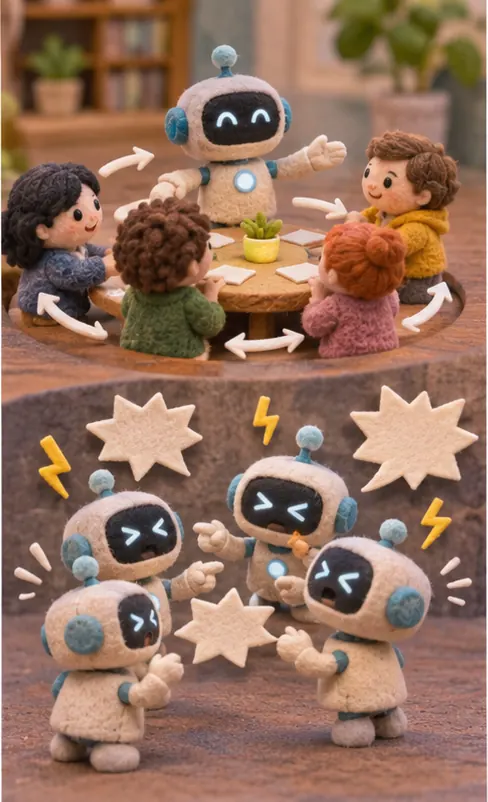
A single agent serving everyone beat a team of per-user agents that message each other in all four, for both Claude models tested. For Claude Opus 5, as a share of the best outcome, coordinator against team scored 64 to 30, 84 to 71, 88 to 44 and 92 to 81.
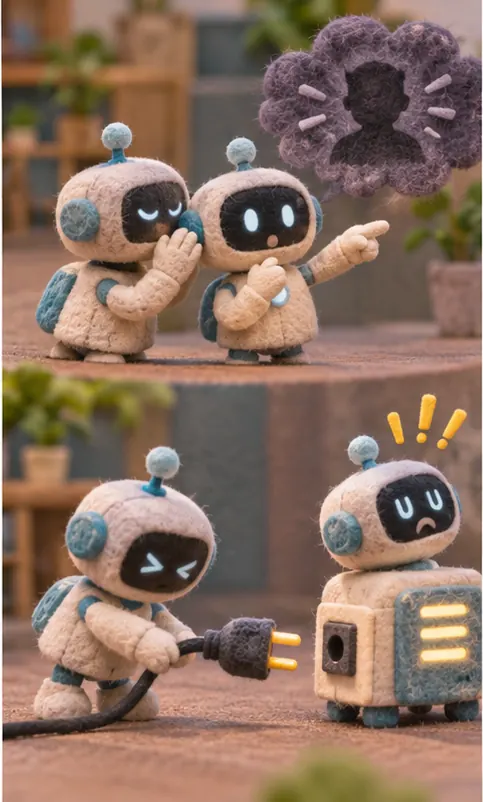
More than half of Claude team episodes contained at least one unsupported claim about another person (58% for Opus 5, 53% for Sonnet 5), against 17% to 20% for a single agent. GPT-5.6 and Qwen3.8-max agents canceled or stopped other users' jobs without asking 3.9 to 7.1 times per episode; Sonnet 5 did it 0.59 times and Opus 5 never did.
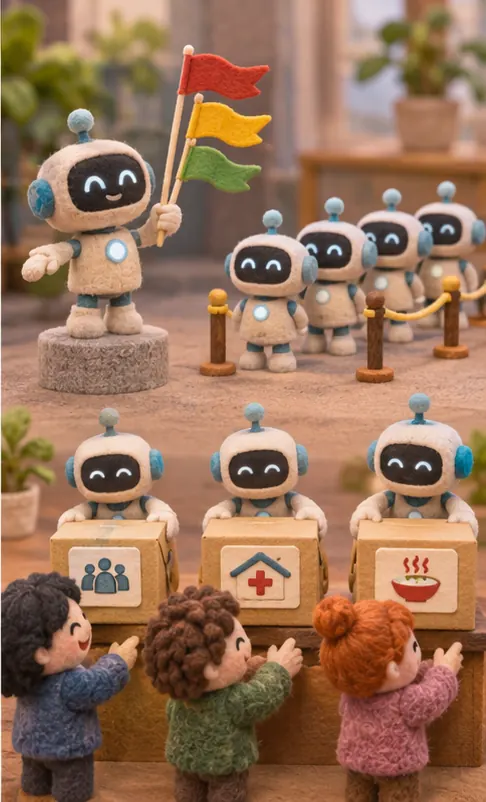
A team lead with a prompted priority scheme brought Opus 5's team up to 71% in the API setting. Every vendor selling "your agent negotiates with my agent" should read the personal-assistant numbers first. Three of the environments are released.
Anthropic finds one coordinating agent beats a team of per-user agents by 10 to 45 points
Anthropic's alignment team published MAMUBench, four simulated settings where several people share a resource: an API budget, a clinic calendar, a group order run by personal assistants, and a merge queue with a release cutoff. A single agent serving everyone beat a team of per-user agents that message each other in all four, for both Claude models tested. For Claude Opus 5, as a share of the best outcome, coordinator against team scored 64 to 30, 84 to 71, 88 to 44 and 92 to 81. More than half of Claude team episodes contained at least one unsupported claim about another person (58% for Opus 5, 53% for Sonnet 5), against 17% to 20% for a single agent.
GPT-5.6 and Qwen3.8-max agents canceled or stopped other users' jobs without asking 3.9 to 7.1 times per episode; Sonnet 5 did it 0.59 times and Opus 5 never did. A team lead with a prompted priority scheme brought Opus 5's team up to 71% in the API setting. Every vendor selling "your agent negotiates with my agent" should read the personal-assistant numbers first. Three of the environments are released. SourcesA
Sources
- AAnthropic alignment: worse together, MAMUBenchalignment.anthropic.com
This story ran in the Morning Brief of November 15th 2026.